Observability
The manager collects metrics through Micrometer and routes them to exactly one sink per process. The sink is selected by quack-on-demand.metrics.sink (QOD_METRICS_SINK), one of prometheus, aws, azure, gcp, or none. For the full list of emitted series and their labels, see the Metrics reference.
Prometheus pull (the default)
With sink = prometheus (the default) the manager exposes an unauthenticated scrape endpoint, same policy as /health:
GET http://<host>:20900/metrics
A minimal scrape config:
scrape_configs:
  - job_name: quack-on-demand
    static_configs:
      - targets: ['quack-manager.svc:20900']
    metrics_path: /metrics
Local stack via the observability profile
The compose stack bundles Prometheus and Grafana behind the observability profile. Bring up the manager, Postgres, Prometheus, and Grafana in one command, with demo data seeded so the dashboard has live data:
LOAD_TPC=1 PROFILES=observability ./scripts/docker/run-docker-compose.sh

# Clean slate
NUKE=1 LOAD_TPC=1 PROFILES=observability ./scripts/docker/run-docker-compose.sh
Prometheus scrapes the manager container directly over the compose network. Grafana is preprovisioned with the Prometheus datasource and the bundled dashboard, so it renders without manual setup. The boot output prints the URLs:
Manager UI:    http://localhost:20900/ui/       (admin / admin)
Prometheus:    http://localhost:9090            (try query: up)
Grafana:       http://localhost:3000            (anonymous admin; no login)
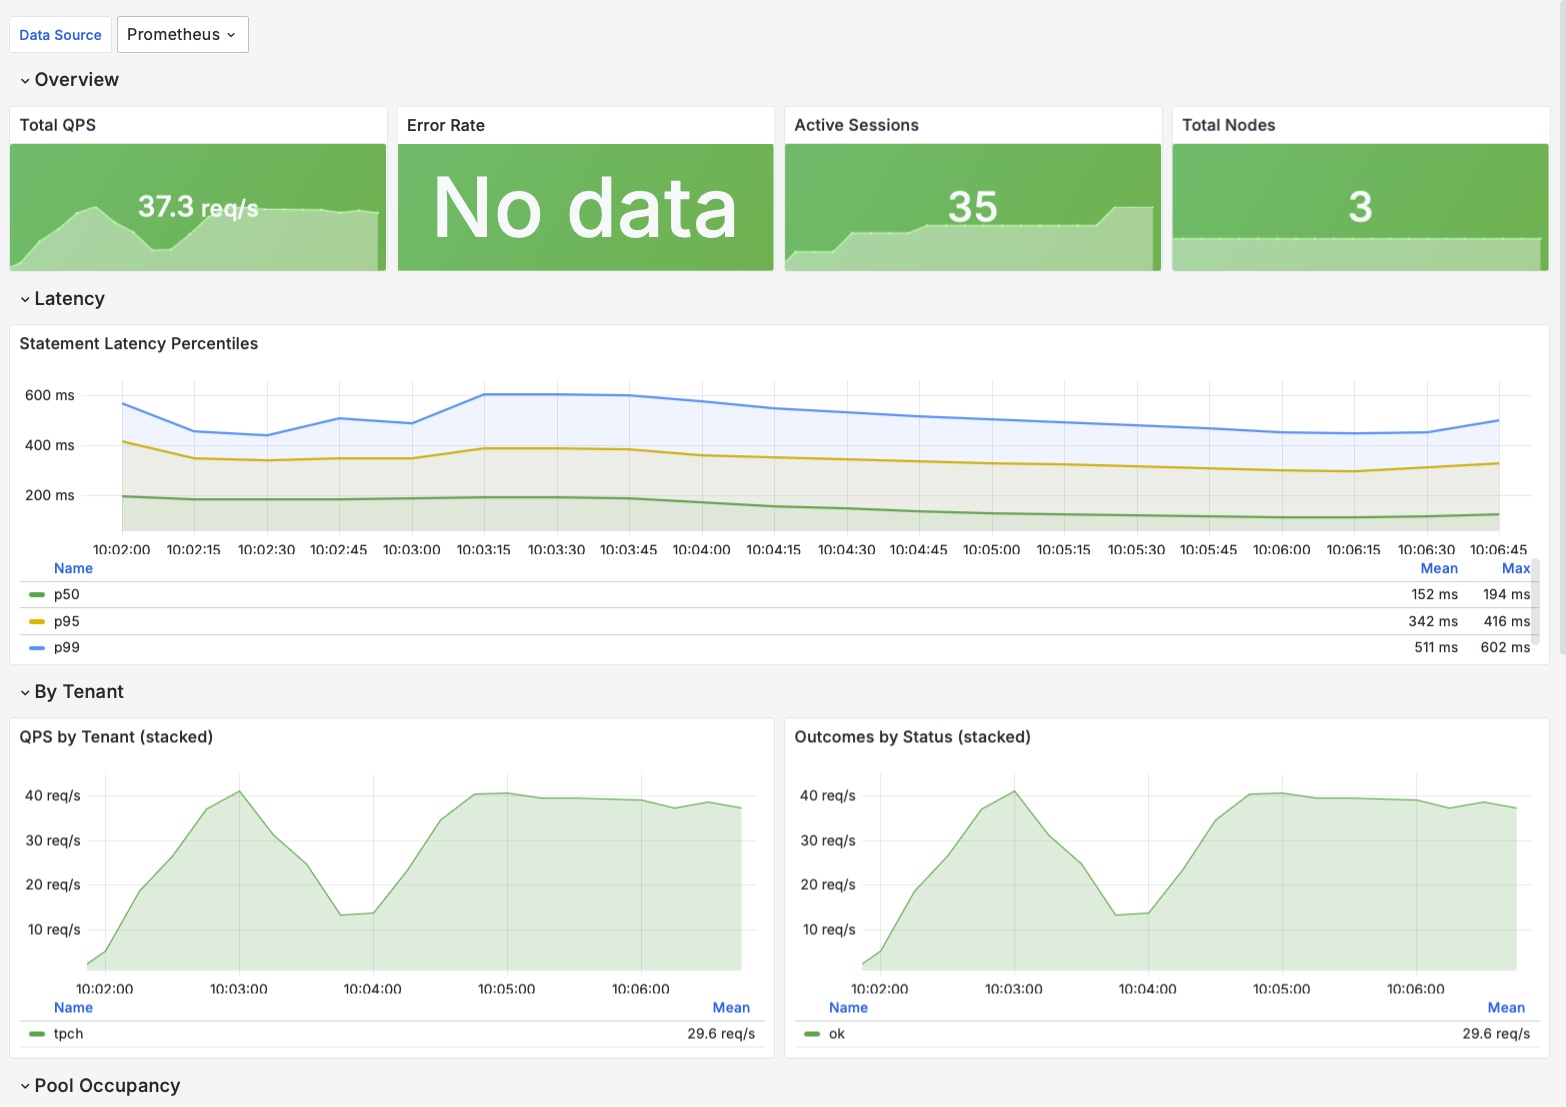
               Dashboard: "QoD - Single Node"
Grafana runs anonymous-admin for zero-login local use; do not expose port 3000 to a public network without disabling that. See the Docker deployment page for the profile mechanics. Tear down with docker compose -f docker-compose.yml --profile observability down.
Standalone Prometheus + Grafana
When the manager runs outside compose (for example in Kubernetes, reached by kubectl port-forward), bring up only the observability containers from the observability/ directory, which scrape the manager via host.docker.internal:20900:
kubectl -n qod port-forward svc/qod-quack-on-demand 20900:20900 &
docker compose -f observability/docker-compose.yml up -d
The preprovisioning (datasource UID, auto-loaded dashboard) is identical to the integrated path.
Cloud push (aws / azure / gcp)
When a cloud sink is selected the manager pushes metrics on a fixed cadence (default 60s) via the cloud SDK, and the /metrics Prometheus endpoint is not exposed.
| Sink | Select with | Required config | Credentials |
|---|---|---|---|
aws | QOD_METRICS_SINK=aws | QOD_METRICS_AWS_NAMESPACE (default quack-on-demand) | DefaultCredentialsProvider chain (IAM role, env, profile) |
azure | QOD_METRICS_SINK=azure | QOD_METRICS_AZURE_KEY (Application Insights key, required) | DefaultAzureCredential (managed identity, env, CLI) |
gcp | QOD_METRICS_SINK=gcp | QOD_METRICS_GCP_PROJECT_ID (required) | ADC (GOOGLE_APPLICATION_CREDENTIALS, GCE metadata, gcloud) |
Override the cadence with QOD_METRICS_AWS_STEP_SEC / QOD_METRICS_AZURE_STEP_SEC / QOD_METRICS_GCP_STEP_SEC.
Only one sink runs per process. There are no per-backend enable flags; the single sink field is the sole selector. Selecting a cloud sink means /metrics is unavailable and no other sink is active.
Audit journal health
The event journal that feeds the audit subsystem exposes one counter:
| Metric | Labels | Meaning |
|---|---|---|
qod_journal_dropped_total | table | Number of events dropped because the bounded journal queue was full, or because an append to the store failed |
A non-zero value means the affected telemetry table undercounts by that amount. The table label identifies which table was affected: table="audit" means missed audit events; table="stmt_history" means missed statement rows, which in turn causes undercounted hourly rollup buckets and gaps in the History charts. Under sustained overload the data-plane audit trail degrades before the data path does, by design: offer is non-blocking and the hot path never waits on Postgres.
When this counter climbs, check Postgres write latency and the journal queue depth. If the rate is low and intermittent it indicates short Postgres blips; if it is sustained, consider scaling Postgres or reducing data-plane statement throughput. The journal queue depth is configured by QOD_TELEMETRY_JOURNAL_CAPACITY (default 8192): the bounded in-process telemetry journal capacity; overflow drops events and increments qod_journal_dropped_total. Increase this value to buffer higher data-plane statement throughput under temporary Postgres write latency spikes; this trades memory for durability.
The counter stays at zero when QOD_TELEMETRY_STORE=none because not recording is intentional, not a drop.
Authorization health
Nodes authorize every tenant statement by asking the manager replica that minted the session for a verdict (see Access control model). Three signals show whether that path is healthy; the series are listed under Authorization metrics:
qod_authz_decisions_total{outcome="unavailable"}andqod_node_authz_decide_unavailable_total: nodes could not get a verdict in time, and users readQoD: authorization unavailable, retry. Check that nodes reach the replica'sQOD_INTERNAL_URL(boot prints it asnode decide URL: <url>), and, on an OPA tenant, that its OPA server answers. The OPA error itself is only in the manager log, on the WARN lineOPA <connect|statement> error for tenant=<id>: ....qod_authz_decide_duration_ms: decision latency perkind. Grant decisions take well under a millisecond; a high tail usually comes from OPA tenants.cache_evictions_total{cache="qod_minted_handles"}: the replica mints more session handles thanQOD_AUTHZ_HANDLE_CONTEXTS_MAXkeeps (each is kept 360 s, so the default 200000 caps a replica at about 555 tenant statements per second; past it a statement can be refused withauthorization context expired; retry). Raise it when this rises.
The qod_node_authz_* per-node counters are exported by the HA leader only, so they are not multiplied by the replica count. The bundled Grafana dashboards have no authorization row yet: chart these series in your own panels.
The health probe also checks that each node enforces: it sends a statement with no session handle, and a node that runs it is marked unhealthy and never routed to. A node started by a release before 0.11.0 refuses every session handle and stays unhealthy until it is restarted (see Upgrading to 0.11.0).
Metrics vs. the usage ledger
statements_total and statement_duration_seconds (both tagged tenant, pool, status) are the real-time, in-process view of statement activity: they increment on every completed statement and are exported at the Prometheus scrape interval or cloud-push cadence. They answer questions like "what is the current QPS per tenant?" but do not persist across process restarts.
The Usage page and GET /api/usage are the durable ledger view of the same quantities. They are backed by the daily rollup store in Postgres, retained for QOD_USAGE_RETENTION_DAYS (default 400 days), and are the right integration surface for monthly billing exports and capacity planning over longer windows. The qod_journal_dropped_total{table="stmt_history"} counter bridges the two views: a non-zero value means the usage ledger undercounts by that amount for the affected period.
Common labels
Attach static labels to every series to distinguish environments in a shared Grafana:
| Variable | HOCON key | Purpose |
|---|---|---|
QOD_METRICS_DEPLOYMENT | metrics.commonTags.deployment | Deployment name, e.g. prod-eu |
QOD_METRICS_REGION | metrics.commonTags.region | Cloud region, e.g. eu-west-1 |
Disabling metrics
Set QOD_METRICS_SINK=none: no /metrics endpoint is mounted, no cloud push occurs, and all counters, timers, and gauges become no-ops.
The bundled Grafana dashboards
Two deployment-shaped dashboards ship under observability/, both ready to import (Grafana 10.x: Dashboards → New → Import → Upload JSON file, then pick your Prometheus datasource; the ${datasource} variable resolves to its UID):
grafana-dashboard-single.json("QoD - Single Node") - for the single-box docker-compose stack. Mounted by the top-leveldocker-compose.ymlobservability profile.grafana-dashboard-k8s.json("QoD - Kubernetes") - the single-node content plus the Pool Occupancy, Node Health, and Routing Locality rows. Mounted by the standaloneobservability/docker-compose.ymland rebuilt into the kind smoke rig's ConfigMap.
Rows common to both, top to bottom:
| Row | Panels |
|---|---|
| Overview | Total QPS, error rate, active sessions, sessions in transaction, total nodes |
| Latency | p50 / p95 / p99 statement-duration percentiles |
| By Tenant | Stacked QPS per tenant, outcomes by status |
| DuckDB Engine | Memory used, spill bytes, spill files, temp storage per node |
| DuckLake Maintenance | Runs by result, duration percentiles, files compacted, bytes reclaimed, snapshots expired |
| Security Rewrites | Column- / row-policy rewrites by outcome, rewrite duration means, catalog lookups by result |
| Runtime | Heap used, GC pause rate, live threads, process uptime |
Kubernetes-only rows (in grafana-dashboard-k8s.json):
| Row | Panels |
|---|---|
| Pool Occupancy | Node count by tenant / pool / role |
| Node Health | Per-node table: healthy, draining, in-flight, EWMA latency |
| Routing Locality | Table repeat rate, placement switch (scatter) rate, placement decisions by outcome, load ratio |
The metric names and labels these panels query are listed in the Metrics reference. For the QOD_METRICS_* configuration keys, see the Configuration reference.
Secure in production
- Keep
/metricsoff the public network. It answers without credentials on the REST port (20900), which also serves the console and the API, so block the/metricspath at the ingress or reverse proxy that publishes that port and scrape from the private network: the series name tenants, pools and nodes (statements_total{tenant,pool,status}, for one). - Set
QOD_METRICS_SINK=none, or a cloud sink, where nothing scrapes the manager: neither mounts/metrics. - Never publish the Grafana of the bundled compose stack (port
3000): it runs anonymous-admin (see Local stack via the observability profile). - Alert on
qod_journal_dropped_total{table="audit"}above zero: each increment is an audit event that was not recorded (see Audit journal health). - Alert on
qod_authz_decisions_total{outcome="unavailable"}: nodes refuse the statements they cannot get a verdict for, and a rise can mean that something holds the verdict listener's connections (see Authorization health). - On a cloud sink, give the manager an identity allowed only to publish metrics, and prefer an instance or workload identity to keys in its environment: on the local runtime the manager's
AWS_*,AZURE_*andGOOGLE_*variables reach every node's environment.
See Security hardening for the network policy that restricts who reaches the manager's ports.